Note
Go to the end to download the full example code.
Data partitions for boosting
The boosting algorithm can use two different forms of cross-validation: cross-validation as stopping criterion (always on), and cross-validation for model evaluation (on by default, test=1). Cross-validation for model evaluation ensures that fit metrics, such as the explained variance, reflect how well the model predicts data that were not used to estimate it; fit metrics computed from the same data that were used to estimate the model would overestimate its predictive power. Both forms of cross-validation require partitioning the data into different segments. The eelbrain.plot.preview_partitions() function is for exploring the effect of different parameters on the way the data is split.
Validation set
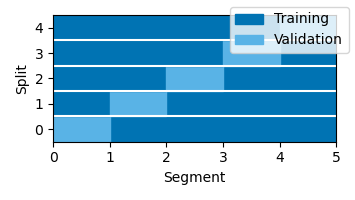
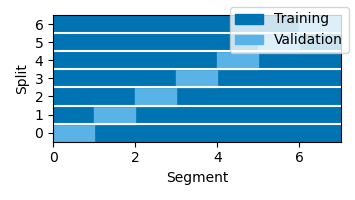
During boosting, every training step consists in modifying one element of the kernel/TRF. After every such step, the new TRF is evaluated against the validation data. To illustrate the validation set by itself, the plots in this section disable the test set (test=0). For continuous data (without Case dimension), the default is then to split the data into 5 equal-length segments, and perform 5 model fits, each using one of the segments as validation set. In the plots below, each “Split” shown on the y-axis corresponds to a separate run of the boosting algorithm. The TRF returned by the boosting() function is based on the average TRF of those 5 runs.
# sphinx_gallery_thumbnail_number = 6
from eelbrain import *


p = plot.preview_partitions(test=0)
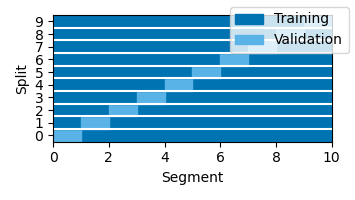
The number of partitions can be controlled with the partitions parameter:
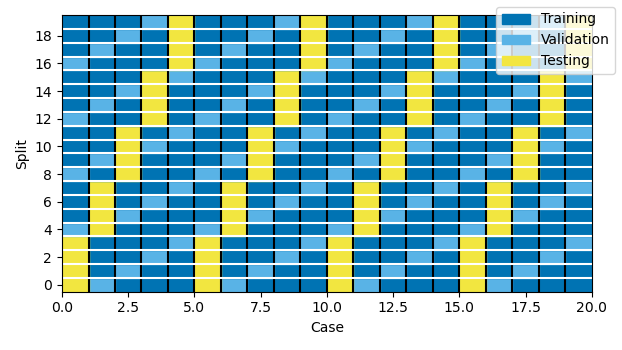
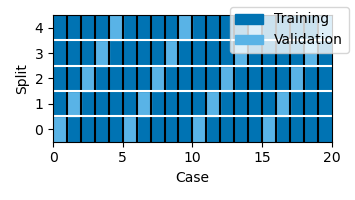
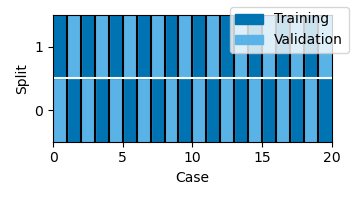
For data with multiple trials (data with a Case dimension), the function attempts to use trials evenly across time:
Validation and testing sets
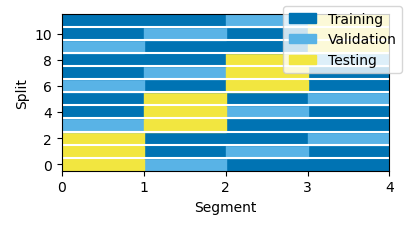
Testing the result of a model fit with cross-validation requires data that was never used during training. This is the default in the boosting() function (test=1): each data segment is used in turn as testing segment. For each testing segment, the remaining segments are used in different runs as training and validation data. The results of those runs are then averaged to predict responses in the testing data. This nested loop means that the number of boosting runs can get large quickly when using many partitions (k partitions result in k * (k - 1) runs), so the default for continuous data is to use five partitions: